Feedback for my wine data analysis project

Hi everyone,

I recently built a small side project called WeinWetterWelt where I tried to estimate the quality of German wine vintages using historical weather data and machine learning:

GitHub:

I am honestly not very experienced with drinking wine myself, which is partly why I am posting here. I would genuinely be interested in hearing what people with much more wine knowledge think about the results.

The project was inspired by Orley Ashenfelter’s work on Bordeaux wines. I combined public wine ratings from the X-Wines database with climate data from the German Weather Service (DWD), mapped weather stations to official German wine regions, and trained Random Forest models on historical vintage ratings.

The three strongest variables in the model ended up being:

  • precipitation during the preceding winter
  • precipitation close to harvest
  • growing season temperature

One thing I found particularly interesting:
Unlike the classic Ashenfelter Bordeaux relationship, warmer growing season temperatures were not nearly as positive for German wines as I expected. In fact, cooler growing season conditions often appeared more favorable in the model. Considering Germany’s strong focus on Riesling and cooler-climate styles, this maybe makes sense — but I would really be interested in hearing opinions from people with deeper wine experience.

Important disclaimer:
I am not claiming weather alone determines wine quality, nor that this can predict whether a bottle will be “great.” I see it more as a climate-based vintage indicator for comparing regions and vintages.

Curious what people here think about the findings and whether they match real-world tasting experience.

have you even done any evals on your output? pretty much every recent vintage for baden is given the label of ‘difficult vintage weather’ with numerical ratings ranging from 14 to 36. just glancing at the wine rating dataset, it does not seem suitable for your task imo.

That is completely possible.

The model does not compare weather conditions within single regions, but instead tries to estimate what “good wine weather” looks like across Germany overall. Since German wine production is strongly dominated by Riesling regions, I am pretty sure the model is somewhat biased toward cooler-climate wine conditions.

I actually checked beforehand whether the regions themselves had systematically different average ratings, and the differences were surprisingly small and not really statistically significant, which is why I left region-specific effects mostly out of the final model.

So a low Baden weather score does not necessarily mean “bad Baden wine.” It could simply mean that Baden weather differs from the weather conditions that are associated with highly rated wines across Germany overall. Baden also grows very different grape varieties compared to regions like Mosel, so it is very possible that warmer conditions work better there but are not captured properly in a Germany-wide model.

I would have loved to build separate regional models, but for many regions there simply were not enough ratings available to train stable machine learning models region-by-region.

And yes, I did some evaluation on unseen test data. I randomly removed 20% of the region-vintage combinations from the dataset before training and then tested the model on them afterward. The model achieved a correlation coefficient of about 0.56 with an R² around 0.31, so the signal is definitely not random — but obviously still far from a perfect predictor of wine quality over all.

What is your goal with this?

It’s pretty obvious that warm dry years produce wines that are richer and fuller. But that’s not the same thing as ‘quality’ these days. Folks around here will argue forever about the subjective nature of wine evaluation.

Sure, you could have a bare minimum standard of distinguishing between ‘quality’ and ‘flawed’ wines. But is that interesting?

It sounds like what you are doing is analyzing the relationship between weather and crowd favorites. But again, that’s not the same thing as ‘quality’, and it’s also not clear what that means, as it is very dependent on who exactly is in the crowd. Although if you’re looking at this from a mass sales angle, that’s a different story.

2 Likes

i would reckon the actual vintage results would be a better indicator of reliable output. reality is a far more robust evaluation than a train/test split from the same distribution. picking another region, the results are no better. rheinhessen 2019 also gets ‘difficult weather vintage’ and a 48 rating. this is widely considered a legendary vintage for dry riesling. of course certain conditions favor different grapes, pradikat/wine styles, etc however it appears your model is not generalizing well. also i would not put so much faith into the stats you cite…

2 Likes

It’s not just “very possible”, it’s a fact.

When the regions are so wildly different, where even climates are different, let alone styles of wines they make, trying to find a one-size-fits-all weather pattern for whole Germany sounds like complete madness.

You need to make it for each individual region (some might evem argue for sub-regions) or this whole exercise is completely useless.

2 Likes

Exactly. I think you’d want to separate out grape varieties where relevant, too. For instance, Rheingau is important for both riesling and Pinot Noir. A given vintage might favor only one or the other.

And it’s not surprising that cooler vintages are generally better for riesling than relatively warm vintages these days.

1 Like

I tried making models for every single region, but the number of ratings from users in the database was too low.

@Otto_Forsberg Thanks for the addition! I can try to separate the data by the different grapes used. That may be interesting in the future.

@m_ristev What exactly are the actual vintage results? Where can I look them up to compare them with my model? Also, what are the ratings based on?

It might not be suitable to compare them directly, as my model is based on user ratings from many people for individual wines. In general, I am confident in saying that the same users can improve their average wine rating by 20%, i.e. by 1 point on a scale from 1–5, if they incorporate the weather ranking from the website in their decision regarding their next wine. Regarding the generalizing: the scores are build to range from 100 best to 0 the worst. The best is Mosel 1990. And the worst is Saale-Unstrut 2014. the rest ist spreaed in between linearly. I dont know how suitable that is. But I wanted a big enough scale for users to rarely find equal rating for easy decision making.

My goal is not to define “true wine quality,” because I completely agree that wine evaluation is highly subjective and depends heavily on personal taste and the type of consumer. I am also transparent in this on my website.

What I am trying to do is much simpler: introduce a weather-based variable into wine-buying decisions and connect it to the perceived ratings of the crowd represented in the dataset. The model is built on ratings from regular users, not professional critics, so in a way it is trying to estimate what weather conditions tend to produce wines that people generally enjoy more.

I am fairly confident that, on average, users who incorporate the weather score into their purchasing decisions would end up selecting wines they personally rate higher compared to choosing completely randomly. The reason I say that is because the vintage-region combinations with higher weather scores consistently correlate with higher user ratings in the dataset.

So yes, I would frame the project much more as a crowd-preference or consumer-guidance tool than as an objective wine-quality model.

In your first post, you said “I tried to estimate the quality of German wine vintages”.

I don’t want to be too negative, if you just like playing around with data and machine learning, then go for it. But from a wine perspective, it’s not particularly interesting to say that the general public tends to prefer wines that are rich and full, which tend to come from vintages that are warm and dry. You don’t need statistical analysis for that.

If you were really interested in tracking the nuances of public wine preferences over time, I wonder if you might get more leverage from looking at the technical info on specific wines that get collected by the state monopolies (e.g. in Scandinavia) and then comparing those to user reviews. That would allow you to be more precise about preferences for specific aspects of wine, seeing how they may evolve over time or vary according to drinkers of specific types of wine, and potentially how they vary across space (if you can geolocate users).

Right now, you are using weather as a proxy for what the wines are actually like, which of course has some general truth. But you are also missing a lot, which you could address with data on the wines’ actual properties.

That said, I would be willing to bet that papers have already been written on this. If you haven’t looked, you might find some in this journal:

4 Likes

many wine publications post vintage charts for regions across the world. the ratings are based on how the growing season progressed, the health and maturity of grapes at harvest, longevity of wines produced, etc. i am certain a simple average of a few vintage charts is far more informative than your model, not to mention quite a bit simpler.

the x wines dataset seemingly comes from vivino. i would guess the ratings there do not mean much, ie low entropy, heavily skewed to 4s and 5s. vivino likely includes a disproportionate amount of ratings for very commercial wines where vintage variation has little influence on the final product.

also what do you hope to achieve with tree based techniques?

2 Likes

This is maybe the 5th example of someone doing something like this that I’ve seen pop up in the last year. It would be an eye-watering amount of work to whip this into something genuinely meaningful. I have given up trying to engage with data analysis hobbyists (or professionals with a side project) trying to connect generic variable A with vague variable B. When I have done so in the past, no one seems to want to actually put in the work to make it useful. So it’s a waste of time getting involved.

2 Likes

And yet you are getting engaged. I am in search of feedback to improve this. I already made a nice list of things for the next iteration. I would be thankful to hear on what you consider as necessary to make this project meanigful.

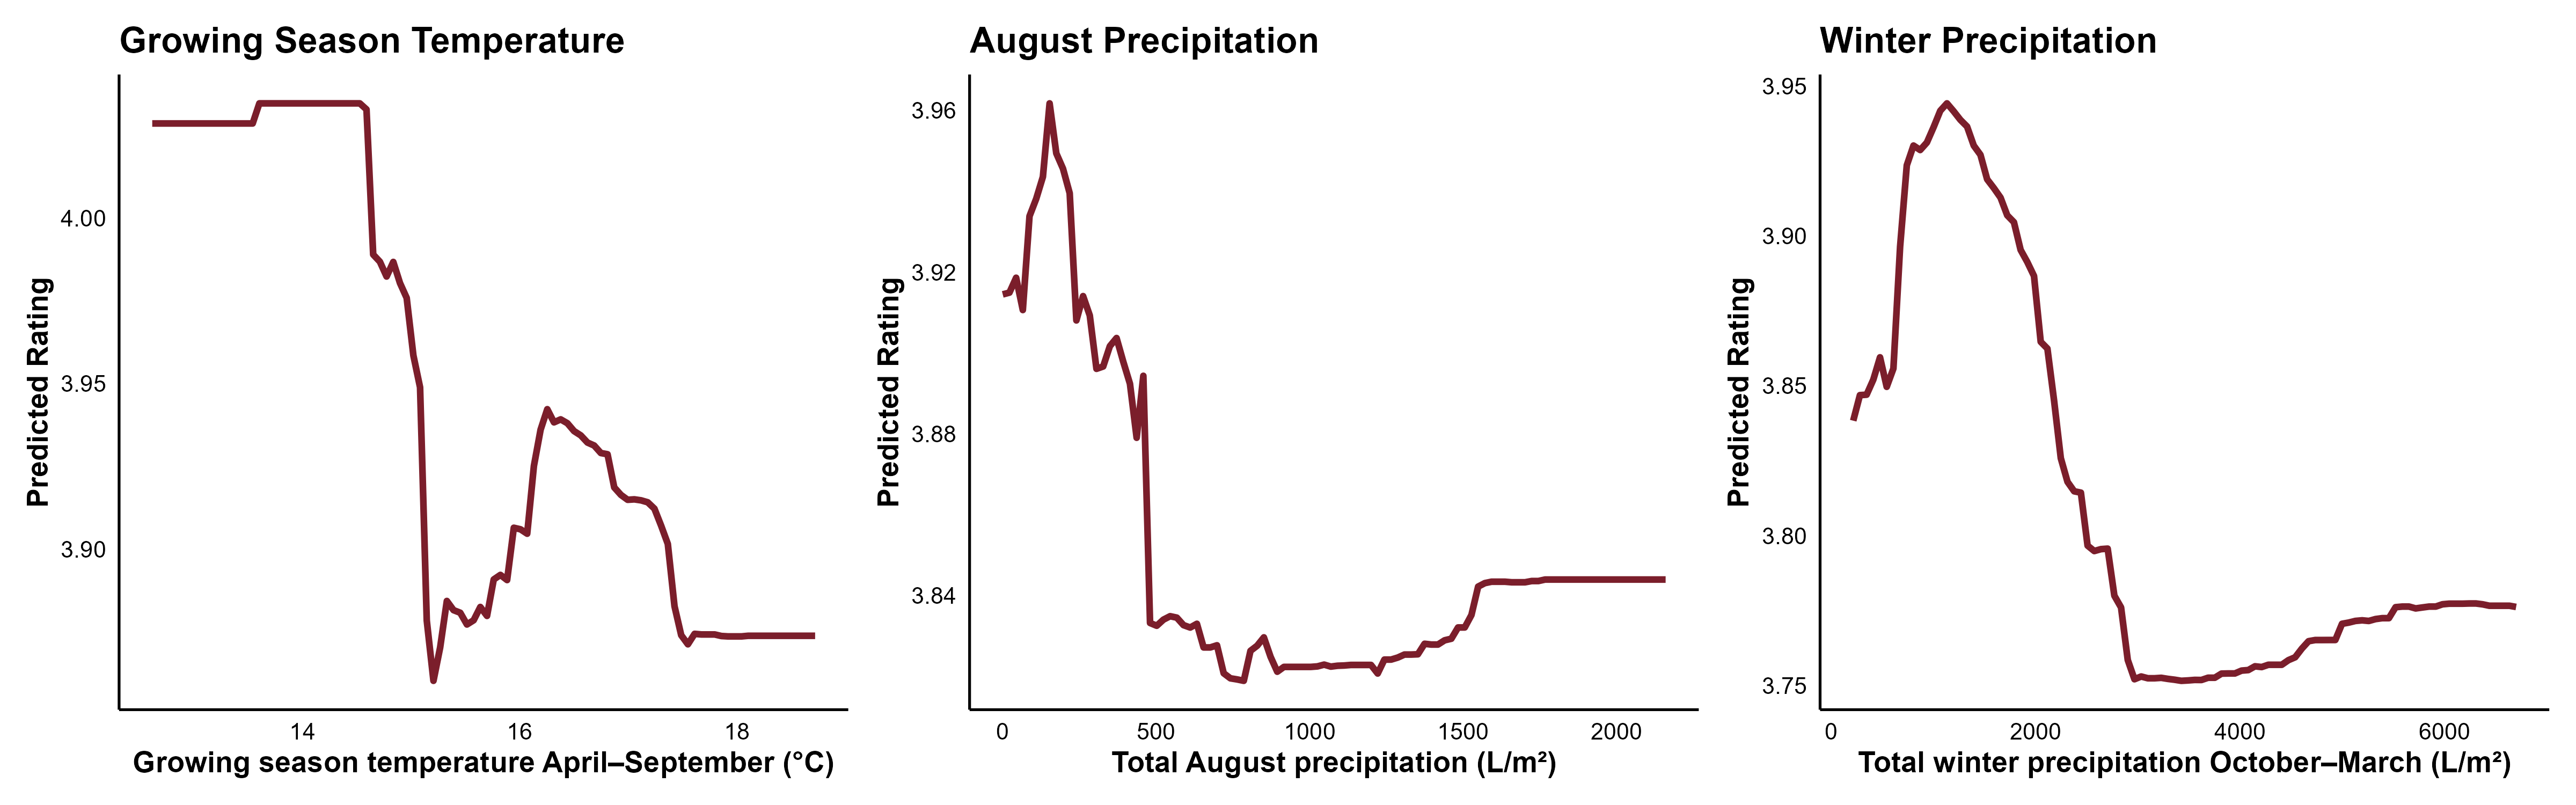
The main issue here is the claim that colder vintages are the best vintages. The growing season temperature graph is problematic in this respect, particularly the flat plateau of high scores for temperatures below about 15.5°C. In reality, years this cool often correspond to vintages from the 1960s, 1970s, and 1980s that are generally regarded as poor rather than exceptional. The suggestion that these conditions are optimal therefore seems questionable.

I suspect this is a consequence of the dataset. If you are using Vivino data, you are relying on a platform founded in 2010. As a result, most wines entered into the database and consumed relatively young come from the warmer vintages of the twenty-first century. By contrast, any wines from cooler twentieth-century vintages that appear in the database are likely to be at least twelve years old and, in many cases, considerably older.

This introduces a significant selection effect. Wines from those cooler years are unlikely to be ordinary mass-market bottles purchased for immediate consumption. Instead, they are more likely to be higher-quality wines that have been deliberately cellared and preserved because they were considered worth keeping. Consequently, the data for cooler vintages may disproportionately represent exceptional wines that survived long enough to be consumed and reviewed, whereas the twenty-first-century data include a much broader mixture of everyday and premium wines.

Unless this issue can be addressed, the model risks comparing fundamentally different populations of wines. The high scores associated with cooler vintages may therefore reflect survivorship and selection effects rather than the intrinsic superiority of cooler growing seasons. This would help explain why the model appears to praise some vintages that are generally considered weak while struggling to account for perceived quality differences in more recent vintages after 2000. Before drawing substantive conclusions about the relationship between temperature and quality, it would be necessary to control for these differences in the underlying sample.

2 Likes

I would never make purchase decisions based solely on an analysis of weather conditions. There are too many other variables and there have been too many wines that have defied weather-based expectations. Tasting notes would always take priority for me.

Thank you for your reply. The temperature data is so variable in the single regions that I doubt visible effects of perceived warmer temperatures now compared to earlier. But I will also do the analysis regarding the real measured temperature differences over the years in the dataset. I find that stuff interesting because I often found no evidence of real warming over the years when I compared temperature data in different projects. I will keep you updated on this. In the meantime:

I changed the website and the training data for the models. Or maybe I should say that I implemented two models: one for red and one for white wine. These two wine types displayed differences in the rating and the growing season temperature. Red wine has higher ratings if the growing season was warm on average. It is reversed for white wine. This seems to be true for France and Germany. I have implemented France too now.

So the reason why my first iteration showed that German wine on average prefers colder temperatures was because German wine is mostly white wine and Riesling. Aggregating the data was hiding the trend for red wine. Please check it out again! PS: The Dataset is a collection of wine experts collected from multiple platforms (https://www.mdpi.com/2504-2289/7/1/20). It is not the vivino database.

Thank you for pointing out these vintage charts. I agree that they are a useful comparison, and I did not know about them until now.

For Germany, I already compared my weather-based vintage ratings with the Best of Wines vintage chart: Vintage chart. On average, the difference for my first version of WineWetterWelt was about 2.5 points on a 10-point scale. That is not perfect, but I still consider it good. I am doing something quite different from what most vintage rating services do. I use a large data collection and estimate ratings from the opinions of the masses, which I find more appealing. I also tried to check how most vintage charts rate their vintages and was kind of disappointed because there was rarely much transparency.

The second version of WineWetterWelt now separates red and white wine. I have not found a suitable vintage chart for that yet for Germany. But I have also added France now, and I am sure that some individual French regions have more available vintage charts from multiple sources than Germany. I will keep an eye out for vintage charts to compare my results to.

Regarding tree-based models: I mainly use random forests because they are useful for an exploratory project like this. I assume that weather variables do not affect wine ratings in a strictly linear way and that they also depend on each other. Random forests are quite good at detecting such non-linear patterns and interactions. They also provide variable-importance estimates, which helps me identify the most relevant weather variables. On the website, I only display a few of them, but I tested more variables in the background.

Thanks for the reply.

I have to say that I’m really surprised about the temperature point. Every graph I can find looks something like this and shows a distinct, accelerating increase from around 2000 onwards. That fits with a great deal of what wine enthusiasts already know from experience, including the much earlier harvest dates we’ve seen in recent decades. So I am quite amazed if the data genuinely isn’t showing any meaningful warming signal.

More generally, I think everyone who has looked at the model is concerned that the outputs don’t seem to reflect anything like the consensus view of which vintages are regarded as particularly good. If we think about where the problem might lie, the model appears to be substantially overrating colder vintages, many of which come from the twentieth century, and I think that probably needs adjusting.

I’m still fairly convinced that the explanation I suggested is the story. There seems to be a sampling effect whereby people are disproportionately drinking older wines that have been deliberately kept because they are good. As a result, a large proportion of the reports you have from twentieth-century vintages are likely to be reviews of unusually successful wines that people chose to cellar. By contrast, reviews from this century are going to include a much broader mix of wines, from excellent to mediocre.

On the white/red distinction that you’ve added, I actually think this supports the point. Nobody is really cellaring old German red wines on anything like the scale they cellar great Riesling. I love Spätburgunder, but very few people are opening 1970s or 1980s Spätburgunders this century and discovering something extraordinary in the way they might with an old Reisling Beerenauslese or similar wine. So the white wine data seems broadly consistent with the hypothesis that long-term cellaring and selective survival are influencing the results.

There are two tests I would recommend.

First, could you restrict the sample to vintages from this century only and see whether the model starts correlating more closely with the warmer years that are generally regarded as stronger vintages? That would remove much of the potential ageing and selection effect.

Second, could you compare the average review scores of wines consumed at very different ages? For example, compare wines reviewed within five years of the vintage date against wines reviewed fifteen years or more after the vintage date. If there is a meaningful score difference between those groups, that would suggest that the model is still systematically overrating older vintages because of the selective survival effect.

2 Likes

First of all, thank you again for this comment. I really appreciate this kind of input because it gives me concrete things to test.

I did both tests you suggested.

First, I retrained the model using only vintages from 2000 onward. The result did not change much. I will attach the updated PDP plot here as well. This is not completely surprising to me, because in the original German model I already used a filtering step: a region-vintage combination was only included in the training data if it had at least 100 ratings. Most very old vintages do not reach that threshold, so they were not actually part of the model training.

I think we may had a misunderstanding. The model was trained only on the region-vintage combinations that passed this filter. The older vintages shown on the website are extrapolated from historical weather-station data, not directly learned from old ratings.

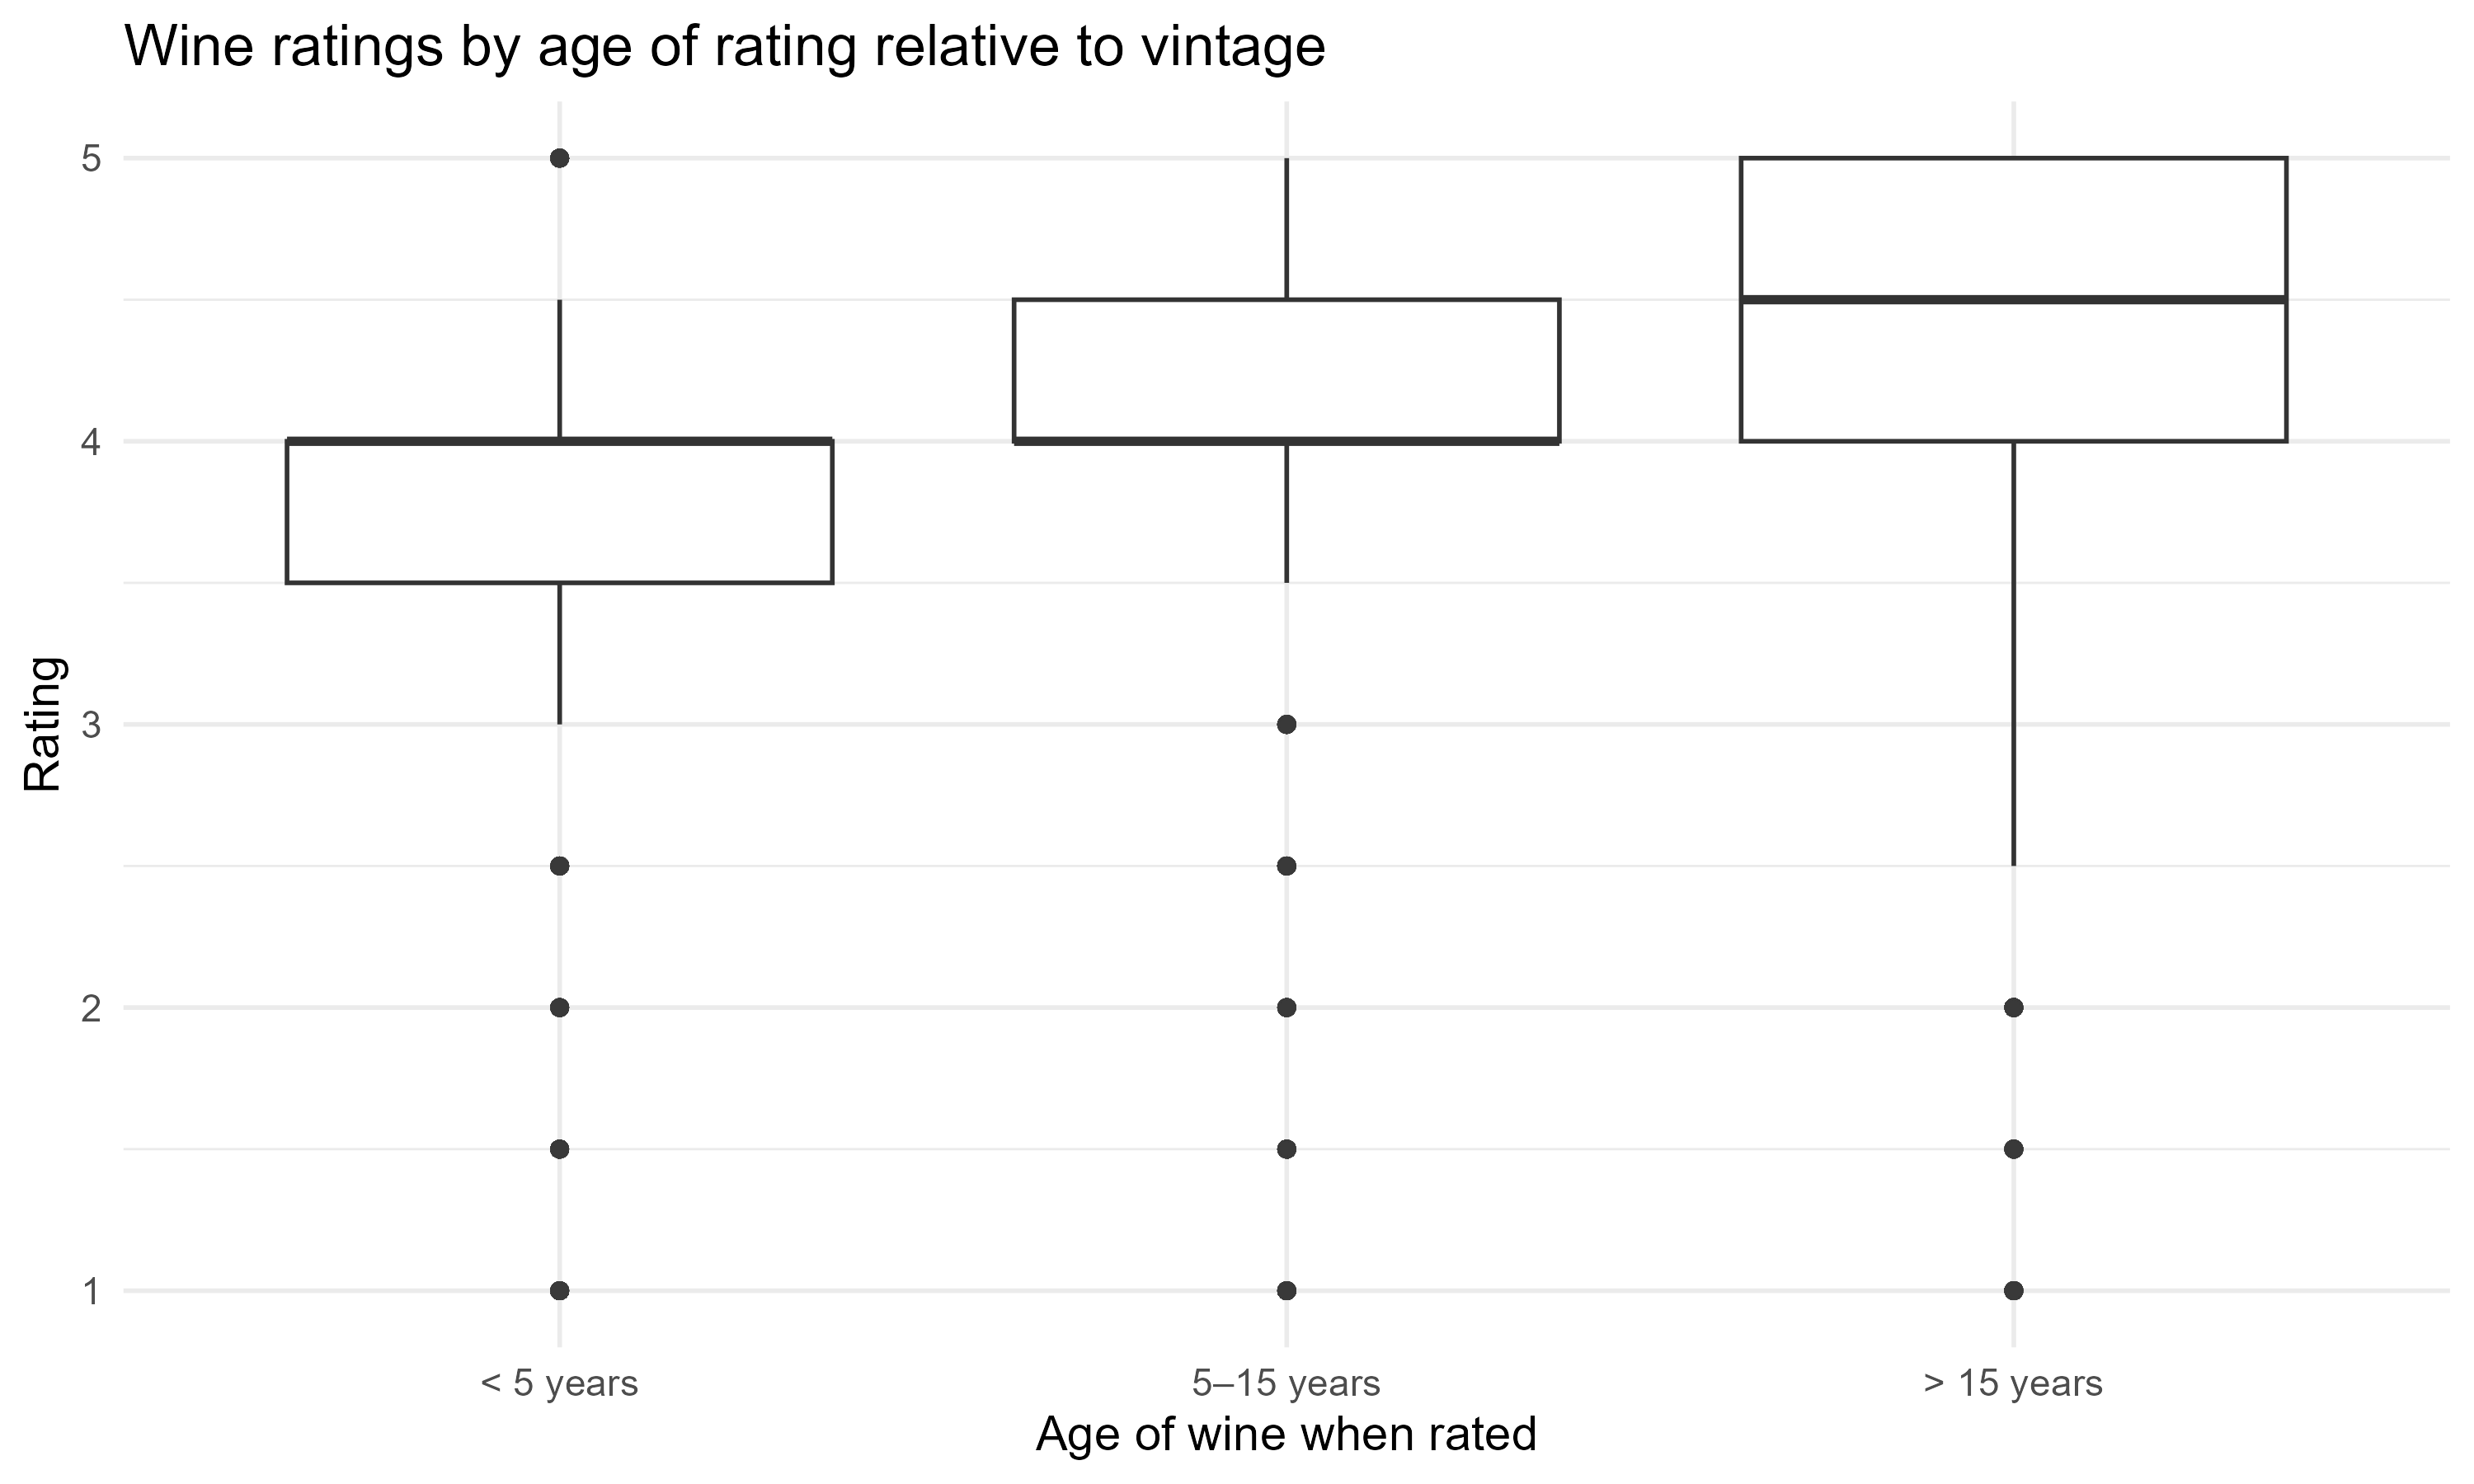
Second, I tested your point about the age of the wine when it was rated. Luckily, the raw rating data contains both the vintage year and the date when the rating was submitted, so I could estimate how old the wine was when it was reviewed. I grouped the ratings into three categories: less than 5 years after the vintage, 5–15 years after the vintage, and more than 15 years after the vintage.

You were right. Older wines clearly receive higher average ratings. Some ratings were even for wines around 70 years old. So yes, there is evidence for a selection effect in the raw rating data. And I plan on correcting for that in future versions!

However, based on the filtering and the 2000-only model test, I currently do not think this age effect explains the main model result. The pattern still seems to be that cooler conditions are associated with higher ratings for white wine.

Regarding the temperature point: I cannot go into detail here while working on WineWetterWelt. I have done several data analysis projects, and in one unpublished project I found enough reason to believe that many datasets showing recent warming trends may be affected by sampling bias. If you want to see the evidence for that claim, you will have to be patient, as I am currently focused on WineWetterWelt. I will also look more carefully at the measured temperature trends within this specific wine-region dataset.

Finally, I want to highlight that I am not disappointed by users here saying that my ratings do not fit what they know from vintage charts. I am doing something different. I recently looked into vintage charts because of feedback I received here. Before that, I did not even know that these charts existed. But I also do not fully understand the concept behind many of them. it is not transparent to me in how they are made and seem to be made by experts for experts, which is fine. I am trying to provide an additional source of information for wine newcomers who just want to explore vintages.

I really appreciate your criticism and your ideas. Please always feel free to ask more.

Here the Plots: PDP Plot for German wine only with Vintage >= 2000 (no seperation between red and white wine, I hope that is what was asked for)

Average ratings based on the rating age of the wine